Why Our Cloud Agent Missed Its Prompt Cache, and What a One-Hour TTL Changed
Foxl's cloud agent read 42.6% of its input from the prompt cache over its first 19 production turns, and every large write followed a gap longer than the cache's five-minute lifetime. A one-hour TTL took a measured nine-call session from 71.8% to 85.7% (93.9% after the first call) and cut its total cost 8%, though a chat that ends within five minutes pays about 23% more than it would with a five-minute TTL. How to measure the ratio, where the four breakpoints go, when the longer TTL pays, and what caps it.
On this page
A prompt cache hit rate is the share of a call's input tokens that the provider read from its cache instead of processing again: cache_read / (uncached input + cache_read + cache_write). Everything here applies to any agent that calls Claude through the Messages API, on Anthropic or on Amazon Bedrock. Our example is Foxl's cloud agent, which answers a user's chats from their phone or the web while their computer is off. Over its first 19 production turns it read 42.6% of its input from the cache, and every large write had the same cause: the cache entries lived five minutes, and people reply later than that.
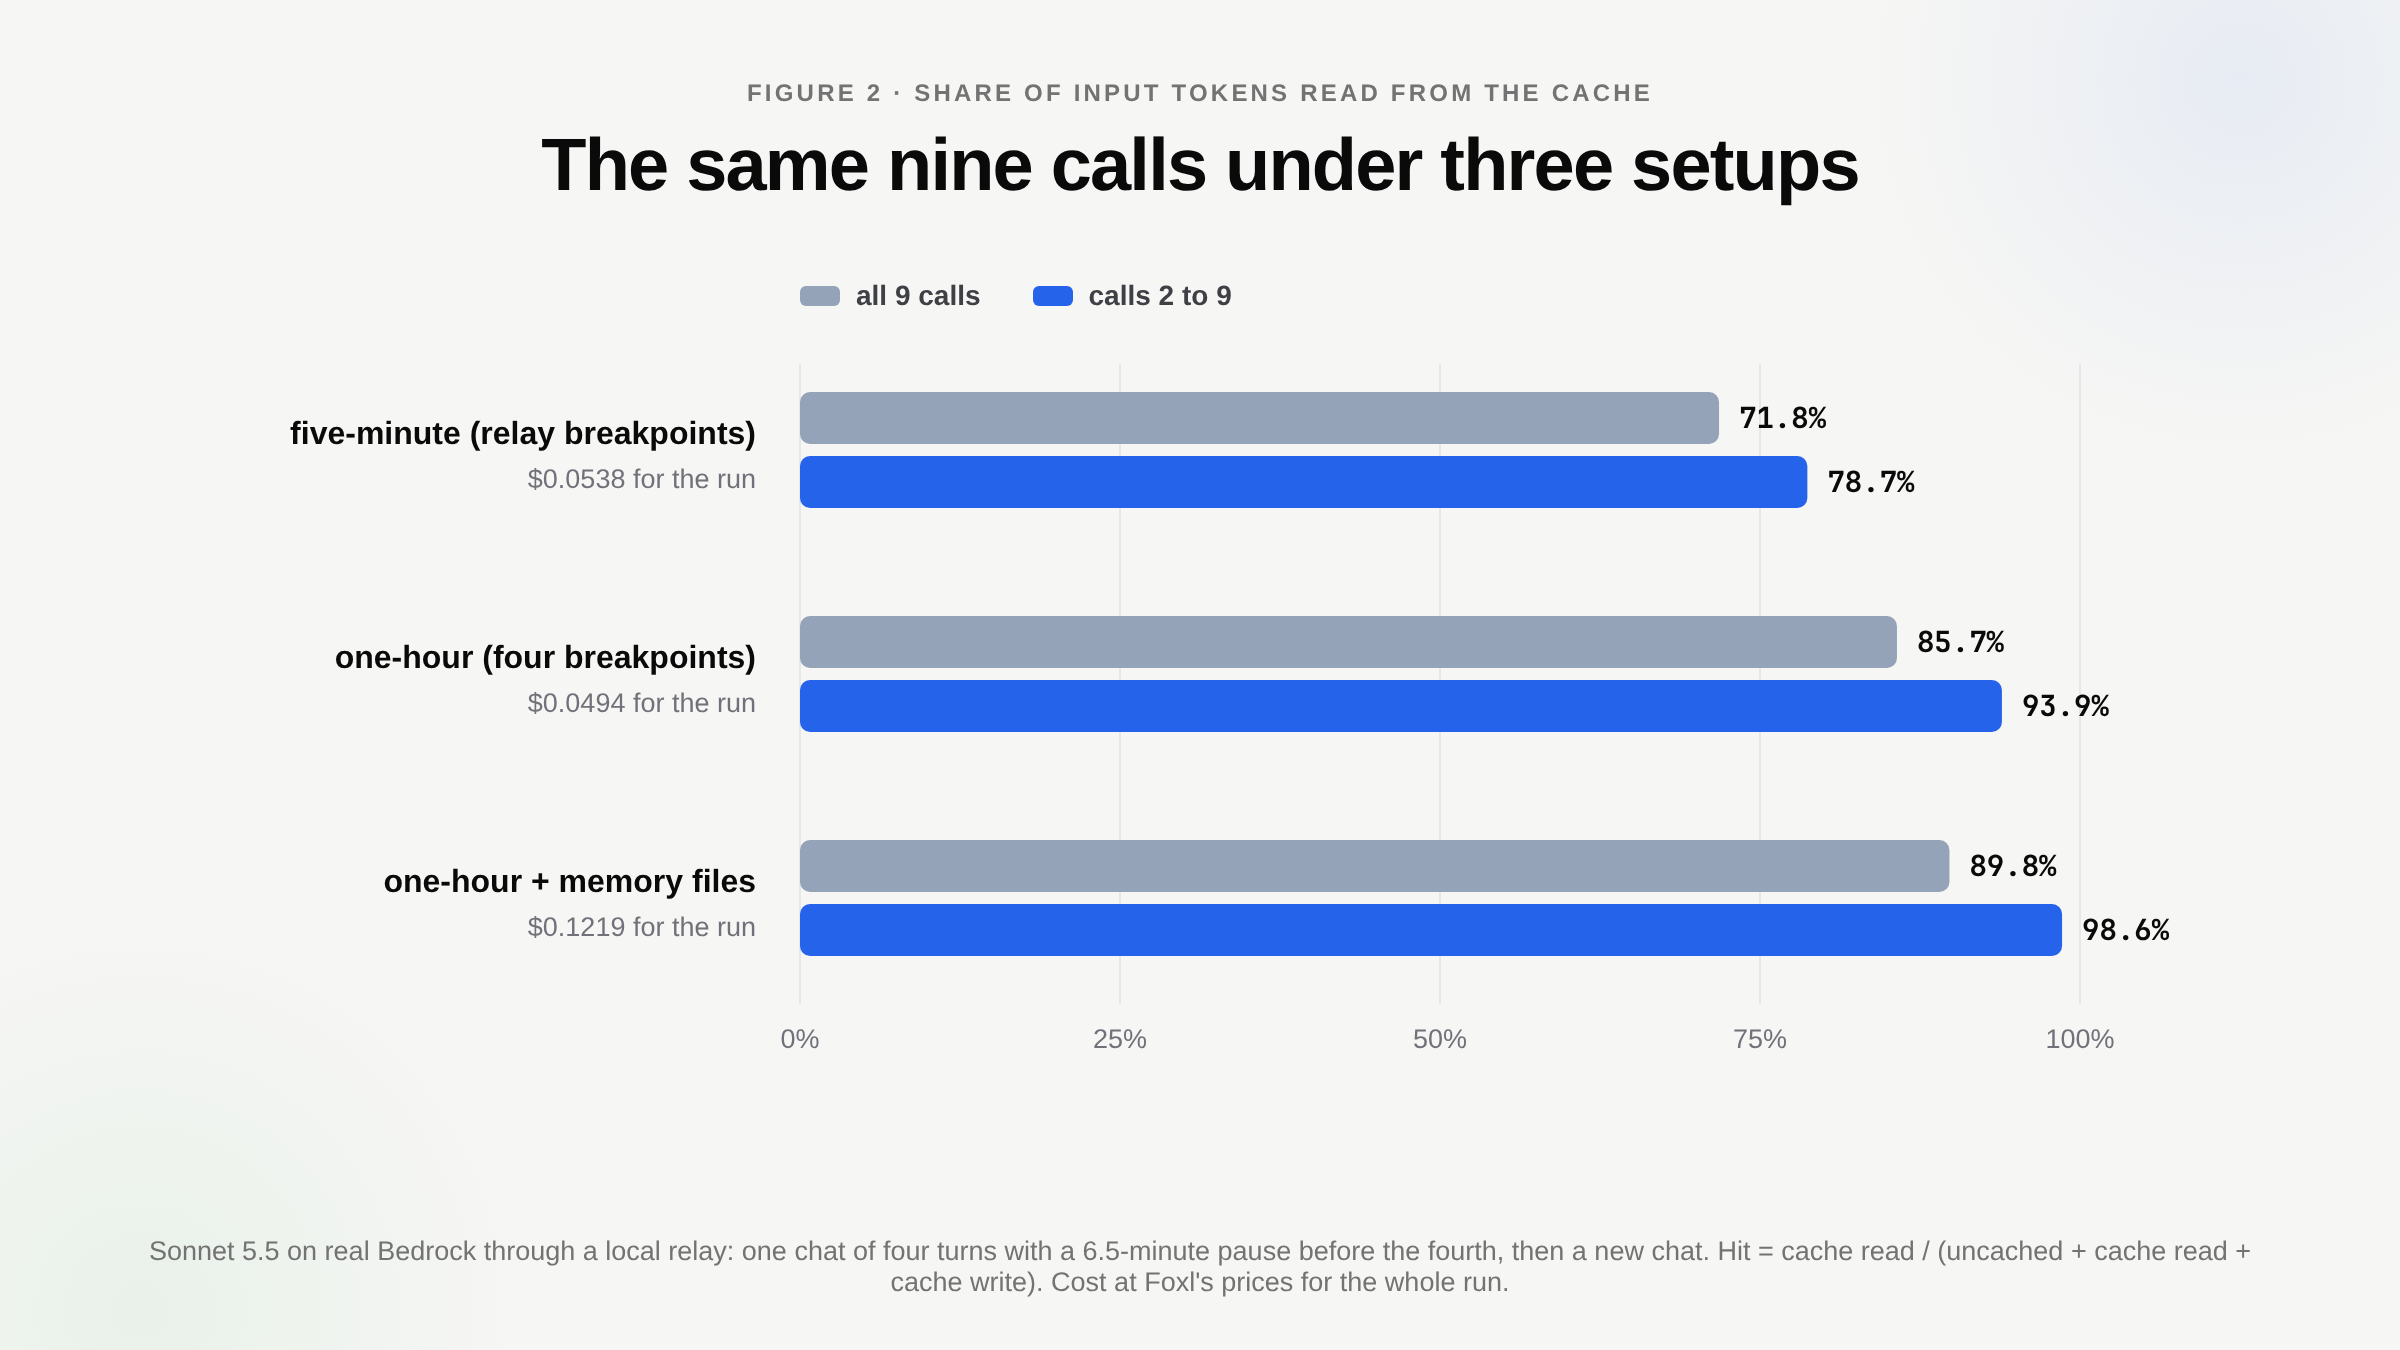
We gave the cache entries a one-hour lifetime and re-ran a measured nine-call session. Its hit rate rose from 71.8% to 85.7%, or 93.9% if you leave out the first call, which always writes. The session cost 8% less in total and 15% less on input, even though a one-hour write costs twice the base input price. The longer lifetime has a price too. A chat that ends within five minutes pays double for every write and never reads one back: with the pause taken out, the same nine calls cost about 23% more under the one-hour setting than under the five-minute one. The change shipped in Foxl v0.9.3-beta.5.
How do you measure an agent's prompt cache hit rate?
First, three terms. A cache breakpoint is a cache_control marker on one block of the request; it asks the provider to cache everything up to that block, which is called the prefix. The entry lives for a TTL (time to live), five minutes by default, and the next request that starts with the same prefix reads it instead of paying for it again. Bedrock calls breakpoints checkpoints.
Every Messages API response reports three input counters, and Anthropic's page puts their relationship in one line: total_input_tokens = cache_read_input_tokens + cache_creation_input_tokens + input_tokens. So input_tokens is only the part that was neither read from nor written to the cache, and a hit rate computed as cache_read / input_tokens is a different, much larger number. Bedrock's Converse API says the same about its own fields: when caching is on, inputTokens "represents only the non-cached input tokens".
We report two figures for every run. The hit rate over all calls includes the first call after the cache has expired, which always writes. The hit rate after the first call shows what a conversation costs once its cache is filled. Part of a prompt can be identical for every user (the first breakpoint below), so in production one person's first call can read what another person's conversation wrote; only the all-calls figure can show that. The test we describe below ran as a single person, so it does not measure it.
We took the production baseline from Foxl's billing records for the cloud agent: 19 turns in 8 conversations since launch, with 35,054 tokens read from the cache, 47,173 written and 72 uncached. 35,054 / (35,054 + 47,173 + 72) is 42.6%. More was written than read: 47,173 written minus 35,054 read leaves at least 12,119 tokens, about a quarter of what the agent paid to cache, that were never read back.
Why does a chat agent keep missing its own cache?
Foxl's relay, the server between Foxl's apps and Bedrock, already added three breakpoints to every Claude request: one on the last tool, one on the system prompt and one on the last user message, all with the default five-minute TTL. While calls came close together, they hit. A follow-up sent 15 seconds after a reply read 3,616 tokens and wrote 44.
Every large write followed a gap longer than five minutes. A message sent 26 minutes after the previous reply, or a chat opened two hours after the last one, wrote the whole prefix again, about 3.6K tokens of tools and system prompt. People on a phone reply when they next look at it. AWS describes this case almost exactly in its guidance for the one-hour cache: "when storing a long chat conversation with a user and you generally expect that user may not respond in the next 5 minutes."
A hit also refreshes the entry for free ("The cache is refreshed for no additional cost each time the cached content is used"). So an agent working through a tool loop rarely notices the five-minute limit, unless one call or one tool takes longer than five minutes. In a chat with a person, the limit bites between turns, which is where that chat spends most of its time.
Where should the four cache breakpoints go?
A Claude request may carry at most four breakpoints (Anthropic: "You can define up to 4 cache breakpoints"; Bedrock gives 4 for every Claude model in its table). The cached prefix is read in the order tools, system, messages, and a change anywhere invalidates everything after it. Because the relay's breakpoints were all five-minute ones, the cloud agent now sets all four itself, each with its TTL. The relay leaves a request that already carries breakpoints alone, so it adds none of its own.
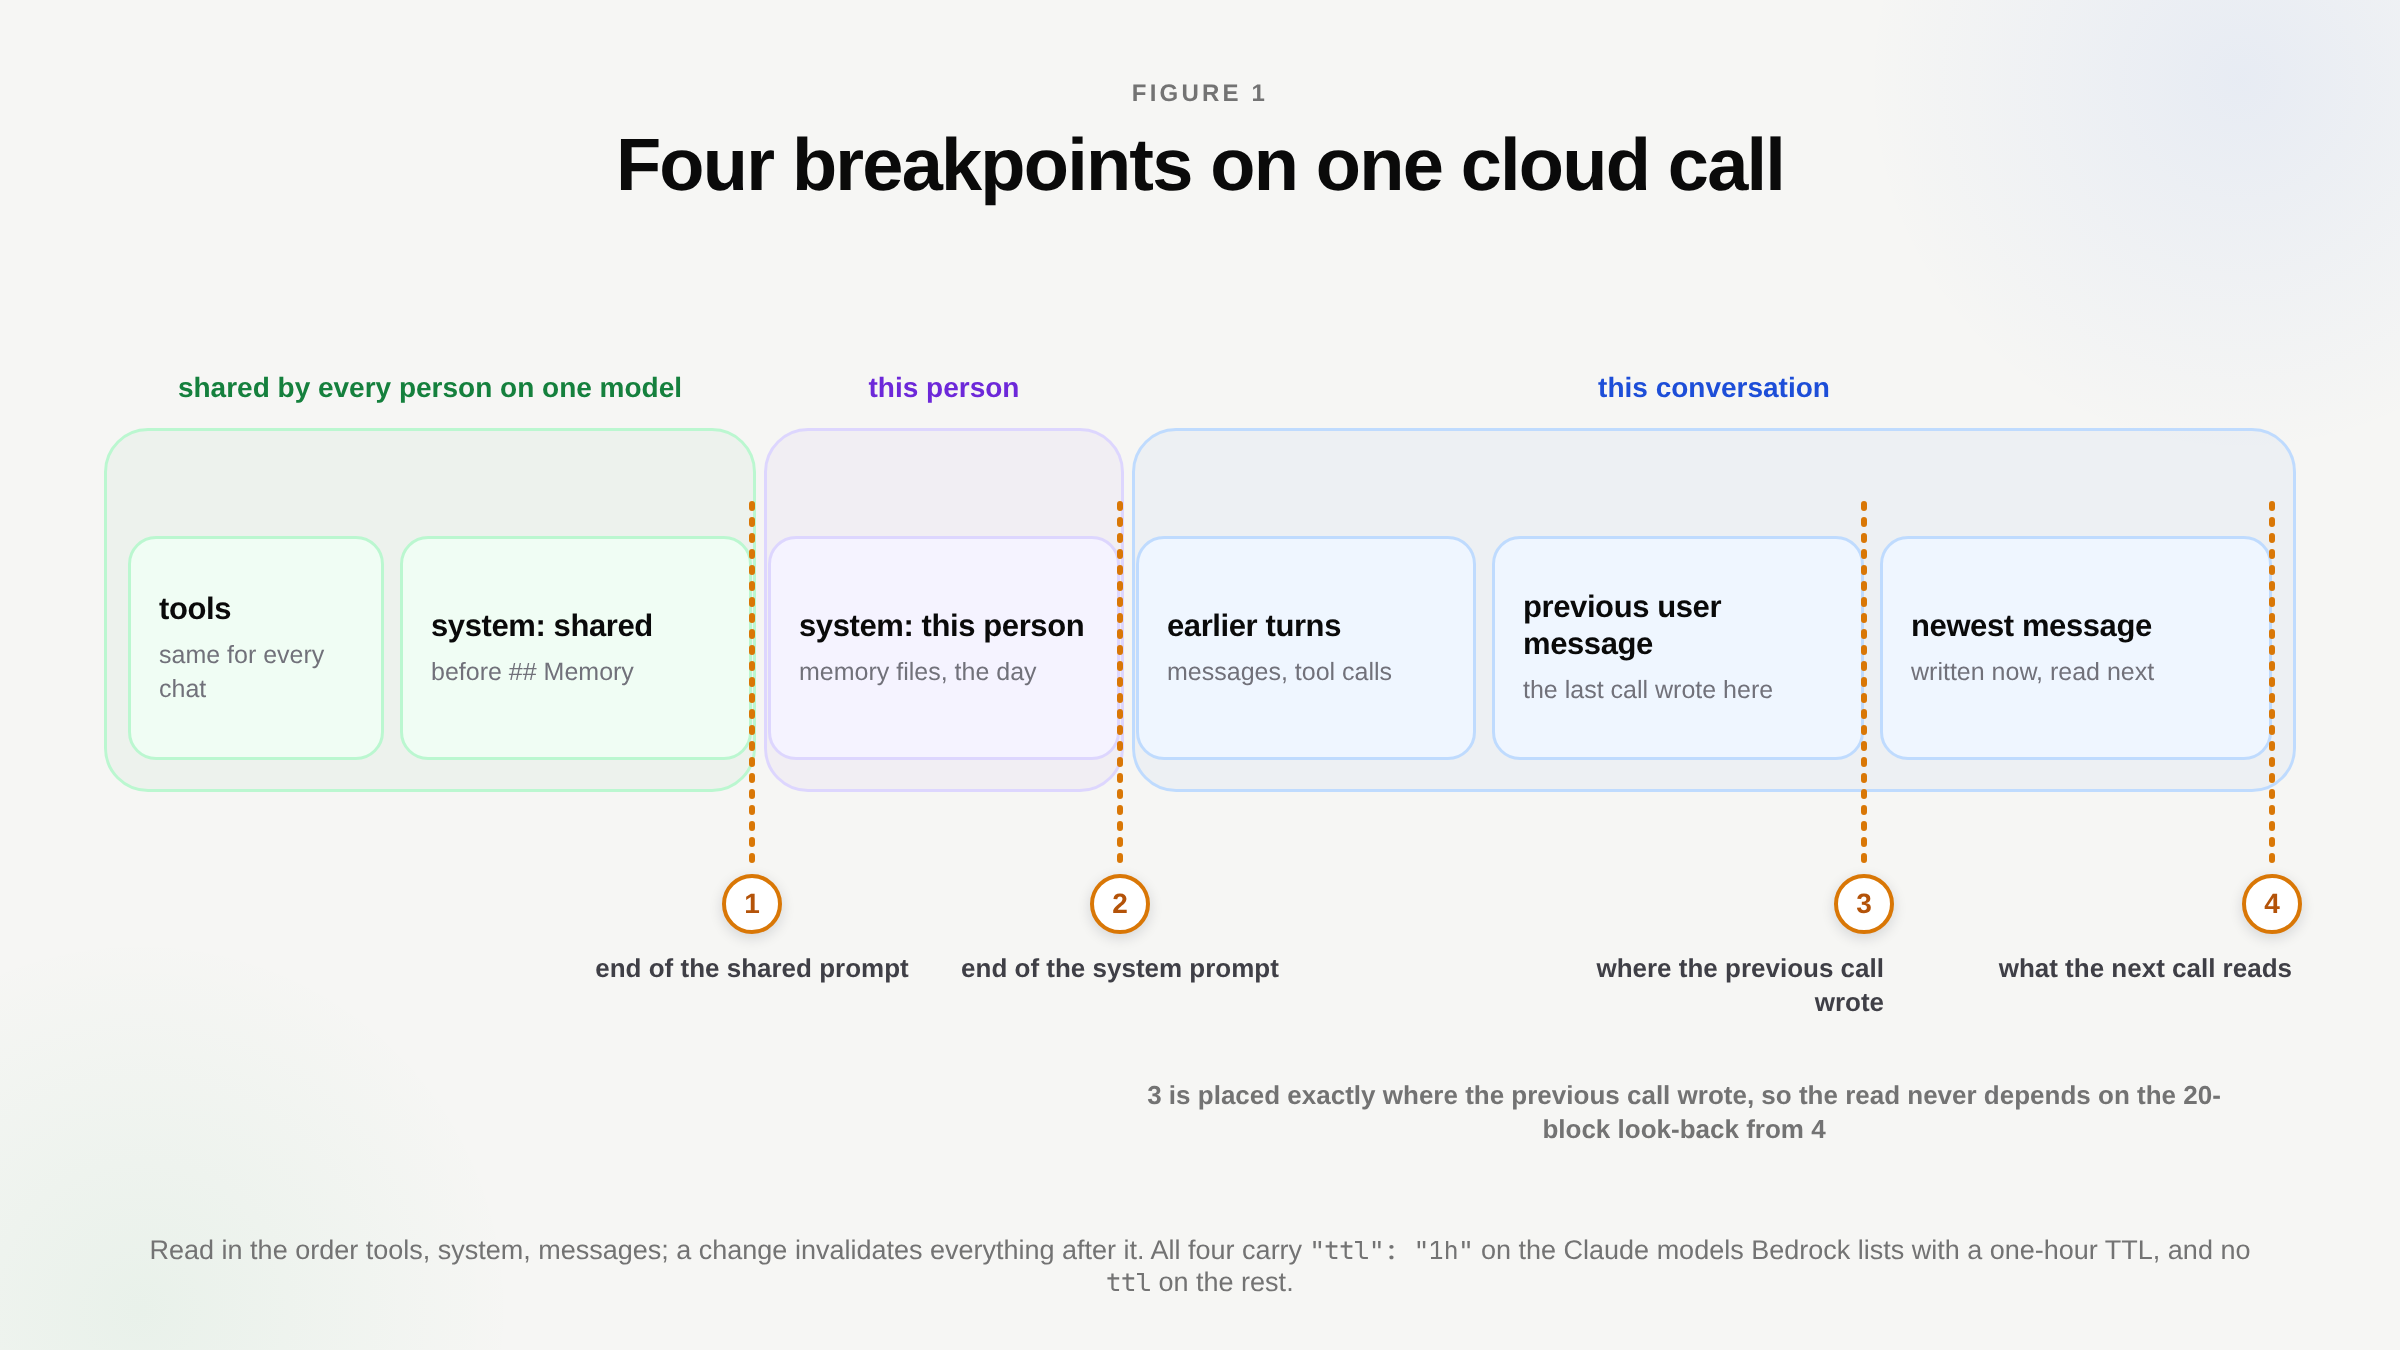
- The end of the shared part of the system prompt. We split our system prompt where the per-user memory begins, at a
## Memoryheading. The tools and everything above that heading (the agent's identity, what it can and cannot do in the cloud) are identical for every conversation of every person on one model, so a brand new chat from anyone starts by reading them. - The end of the system prompt. The second breakpoint adds the person's own memory and a date line. The date line gives the day, not the time, so it does not change the prefix between calls.
- The last cacheable block of the previous user message. This is exactly where the previous call wrote, so the read never depends on the API's look-back rule. Without it, the API starts at the newest breakpoint and looks back for an earlier cache entry, but only so far ("The lookback window is 20 blocks"), and a turn with many tool calls can push the previous write out of reach. How those blocks count depends on where you call Claude: on Anthropic's API a run of consecutive
tool_useortool_resultblocks counts as one position, while Bedrock's page says only "approximately 20 content blocks" and makes no such exception. - The last cacheable block of the newest message. This is the write that the next call will read.
All four carry the same TTL. Bedrock accepts both TTLs in one request as long as every one-hour entry comes first ("a 1-hour cache entry must appear before any 5-minute cache entries"), and one TTL for all four keeps that true by construction. Breakpoints go only on text, image, document, tool_use and tool_result blocks, which is the message content Anthropic lists as cacheable.
We send the one-hour TTL only to the Claude models that Bedrock's table lists with "Supported TTL: 5 minutes, 1 hour". Bedrock warns that sending the field to a model that supports only five minutes "can result in a ValidationException", so every other Claude model gets the same four breakpoints without a ttl. GPT-5.6 and later on Bedrock are left alone: they use their own prompt_cache_breakpoint field and, per the same page, a "30-minute minimum TTL".
// the marker on each of the four blocks, on a model that takes it
"cache_control": { "type": "ephemeral", "ttl": "1h" }
One more rule decides whether a breakpoint caches anything at all. Bedrock caches a checkpoint only if everything before it reaches the model's minimum length: 512 tokens on the 5.5 models, and 1,024 or 4,096 on some older ones. Below the minimum, "your inference still succeeds, but your prefix isn't cached". So on a model with a 4,096-token minimum, a 3.6K-token prompt leaves the tools-and-system breakpoints caching nothing until the conversation itself pushes the prefix past the minimum. Check the table for every model you serve.
Does a one-hour cache cost more than it saves?
Per Anthropic's pricing, a five-minute write costs 1.25 times the base input price, a one-hour write costs 2 times, and a read costs 0.1 times (0.05 times on Opus 5.5 and Sonnet 5.5). A one-hour write therefore costs 0.75 times the base price more than a five-minute write (2 minus 1.25). You pay that premium on the prefix once an hour, and on each call's new content every time. In return, a pause longer than five minutes no longer rewrites the whole prefix at 1.25 times; the prefix is read instead.
To measure it, we ran the cloud agent's production code through a local copy of our relay against real Bedrock. The scenario is one chat of four turns (a plan tracked with a tool, a follow-up, a file save, then a question about the first turn 6.5 minutes later), then a new chat: nine model calls on Sonnet 5.5 in all, since a turn that uses a tool makes more than one call. Usage was read from the stream Bedrock returned. The cost column uses Foxl's own per-token prices for Sonnet 5.5.
| setup | cache read | cache write | hit, all 9 calls | hit, calls 2-9 | cost of the run |
|---|---|---|---|---|---|
| five-minute (the relay's breakpoints) | 29,979 | 11,755 (5m) | 71.8% | 78.7% | $0.0538 |
| one-hour (four breakpoints) | 35,859 | 5,974 (1h) | 85.7% | 93.9% | $0.0494 |
| one-hour, plus memory files (explained below) | 177,347 | 20,108 (1h) | 89.8% | 98.6% | $0.1219 |
The call after the 6.5-minute pause is almost the whole difference. In the five-minute setup it wrote its 5,873-token prefix again. In the one-hour setup it read 5,750 tokens and wrote 133, and Bedrock reported every write as ephemeral_1h_input_tokens, which is how we know the longer TTL was honored rather than silently ignored. The one-hour run read 5,880 more tokens than the five-minute run (35,859 minus 29,979); that one call accounts for 5,750 of them, and the other 130 or so came from moving the breakpoints. This scenario had no turn with many tool calls, which is what the third breakpoint is for. Uncached input stayed at 28 tokens in every run.
The five-minute setup scores 71.8% in this test where production scored 42.6%, because the test has one gap of 6.5 minutes, while production's 19 turns were spread over 8 conversations with gaps of 26 minutes and two hours. The same code scores very differently on different traffic, so compare hit rates only between runs of the same scenario.
The arithmetic reverses for a chat with no pause. Take the pause out of the same measurements and the five-minute setup never rewrites its prefix, so it is the cheaper one. The one-hour run then costs about 23% more in total and about 48% more on input tokens, because it paid twice the base price for every write and nothing after minute five read them back.
To decide for your own traffic on Sonnet 5.5 or Opus 5.5, compare two numbers:
- Savings: each prefix token that a pause would have forced you to rewrite saves about 1.2 times the base price (a 1.25 rewrite replaced by a 0.05 read).
- Premium: every token written in that hour costs 0.75 times the base price more (2 instead of 1.25).
The one-hour TTL wins when the savings exceed the premium. A chat with a pause between five and sixty minutes usually clears it, and so does a second chat started within the hour; a chat that is over within five minutes, with nothing else in that hour, cannot. For a person answering from a phone we chose the one-hour TTL. For an agent whose calls arrive seconds apart, keep five minutes.
If you reserve credit before each call, the TTL also changes the reservation. Foxl's relay reserves for the worst case, so a request that asks for a one-hour TTL is reserved at the one-hour write rate. That rate (2 times) is 1.6 times the five-minute rate (1.25 times), so a Sonnet 5.5 call with 100K tokens of context reserves about $0.40 of input instead of $0.25. The charge is still what the call used; only the reservation grows, so a nearly empty balance can be refused one call sooner.
What limits a prompt cache hit rate?
The ceiling is set by new content. Every new user message and every reply is written to the cache once before it can be read, so no placement of breakpoints can make a call read the tokens it is adding. In the one-hour run the first call read nothing, because the earlier run's five-minute entries had expired, so all 35,859 tokens read came from calls 2 to 9: 93.9% of the roughly 38,200 input tokens they took. The other 2,300 or so were that run's new messages and replies, so 93.9% was that scenario's ceiling, and no breakpoint could have raised it. A longer chat carries more history per new token, so its ceiling is higher.
A bigger stable prefix also raises the ratio, without making anything cheaper. We saw this when the cloud agent gained an option to include the user's memory files: four Markdown files (SOUL.md, USER.md, MEMORY.md and AGENTS.md) that Foxl's desktop app puts in its own prompt. The phone or browser copies them while the computer is connected, trims them with the same code the desktop uses, and sends them with each cloud message. One real set of these files, trimmed that way, came to about 41K characters, roughly 14K input tokens per call; the third run used a test file of the same size.
In that run the first call wrote 17,619 tokens of the person's prompt, every later call read them, and the hit rate after the first call reached 98.6%. The run cost $0.1219 against $0.0494, because the prompt is several times larger; without the cache the same nine calls would have cost $0.4187. So report cost next to the hit rate: this run had the best ratio and the largest bill.
What does this measurement not cover?
- Production after the change. As of 2026-10-23 there has been no cloud turn in production since the change was deployed, so the 42.6% is the only production figure, and the after figures come from the local relay on real Bedrock.
- Other models. Only Sonnet 5.5 was run. The other Claude models that get the one-hour TTL get it on the strength of Bedrock's table and, for Opus 5.5, an earlier measurement of our relay.
- Other scenarios. Nine calls in one pattern, none of them a turn with many tool calls. A chat that sits idle for over an hour pays the first write again, and one hour is the longest TTL either provider offers for Claude.
If you run Claude agents of your own, the cheapest check is the hit rate itself: add up the three counters per call, compute read over all input, and look at what came before each call that wrote a large prefix. If it followed a gap longer than five minutes, a one-hour TTL is the fix, as it was for nearly all of this scenario's gain. If it followed a call seconds earlier, either the prefix changed between the two calls or the previous write was out of the look-back's reach, which is what the third breakpoint guards against. We wrote earlier about keeping a subagent on its parent's cache, which is the same prefix rule seen from inside one turn.
References and further reading
- Anthropic: Prompt cachingDocumentation
- Amazon Bedrock: Prompt caching for faster model inferenceDocumentation
- Foxl v0.9.3-beta.5 releaseRelease